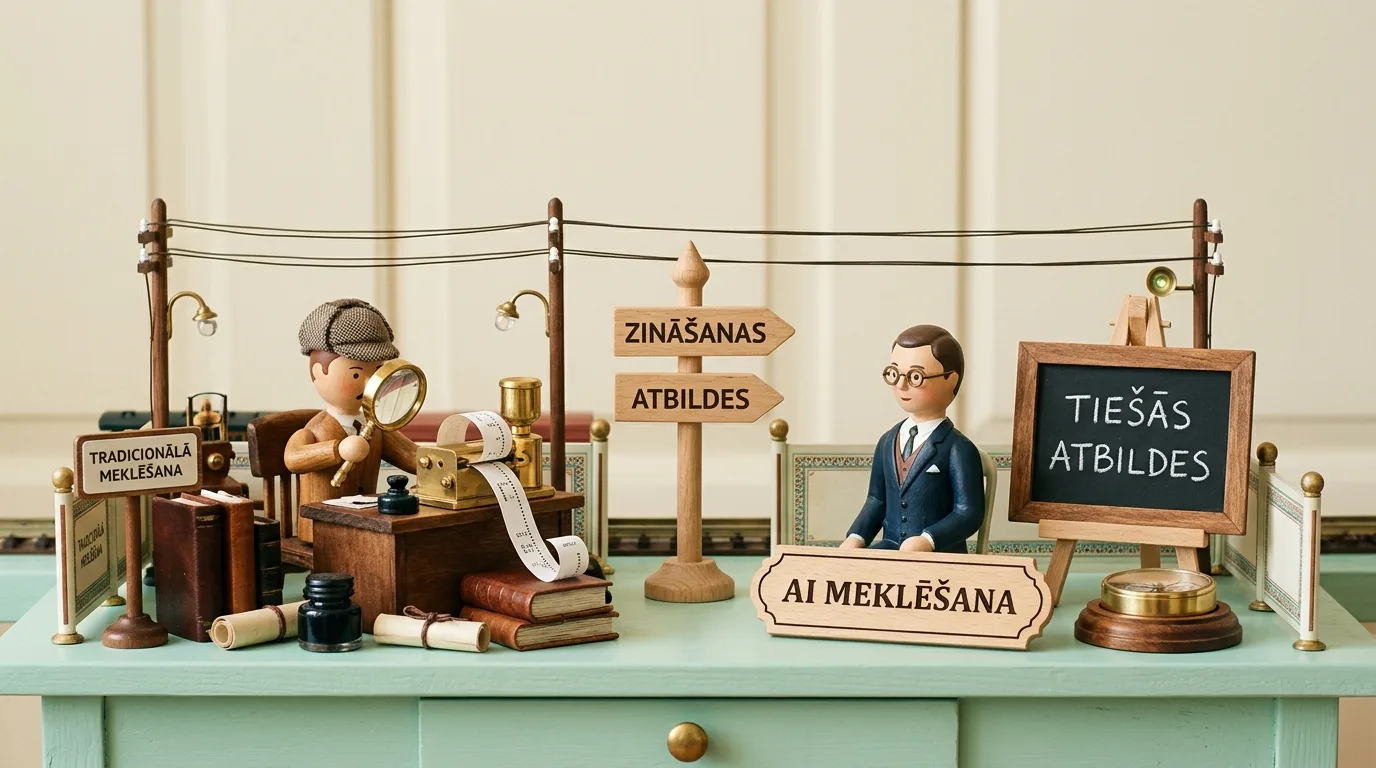
OpenAI ChatGPT Search's official integration into daily search by 2026 has created the first serious alternative to Google's 25-year monopoly. Instead of offering users 'ten blue links' on an ad-saturated page, ChatGPT Search utilizes the OAI-SearchBot real-time indexing crawler and large language model synthesis, providing an immediate, in-depth answer with direct citation links. This means businesses must radically change their content strategy: classic keyword density optimization no longer yields results. This article thoroughly analyzes the differences between the two search engines and provides a technical guide for preparing your website for the new wave of AI content consumption.
For decades, search engine optimization (SEO and GEO) relied on the same rules: find high-volume keywords, include them in the H1 heading, first paragraph, and META description, acquire backlinks, and wait for Google to grant a spot on the first page. This model generated millions of identical, superficial articles whose sole purpose was to satisfy algorithm requirements.
With the advent of ChatGPT Search in the search market, this model is undergoing a tectonic shift. Users, especially in the B2B segment and technical industries, are increasingly abandoning manual sifting through Google results, instead posing complex, multi-stage questions to artificial intelligence assistants. If your company's content is not prepared for AI crawler requirements, you become completely invisible to a rapidly growing and affluent audience.
How ChatGPT Search's Synthesis Engine Works
The main difference between Google's traditional search and ChatGPT Search lies in how information is processed and presented to the user. Google's priority has always been to display a list of results, as each results screen provides an opportunity to sell Google Ads advertising space. In contrast, OpenAI's goal is to instantly solve the user's problem in a single synthesized answer.
When a user enters a query into the ChatGPT Search environment, the process unfolds in 4 lightning-fast stages:
- Query Intent Deconstruction: The language model breaks down the query into several sub-queries. For example, the question 'What is the best B2B website development approach with high conversion?' is transformed into search vectors for cognitive ergonomics, loading speed, and funnel architecture.
- Real-time Web Crawling: The OAI-SearchBot crawler reads the content of dozens of authoritative websites in real-time, searching for precise definitions, factual data, and comparisons.
- Semantic Synthesis: The model compiles the acquired data, eliminating verbose language and advertising clichés, and formulates a structured, readable answer with tables and bullet points.
- Direct Citations: Each statement included in the answer is accompanied by an interactive reference tag that leads directly to the relevant paragraph on the specific website.
"In traditional search, victory went to those who mastered keyword density and accumulated more backlinks. In the era of AI search, victory goes to those who can formulate a crystal-clear answer within the first 50 characters of text. If your article begins with 'In today's dynamic world,' the ChatGPT crawler will simply ignore it and cite your competitor, who placed a specific fact, formula, or cost estimate in the first sentence."
Technical Protocol - OAI-SearchBot and robots.txt Configuration
A large number of businesses unknowingly cut off their AI search traffic by erroneously blocking all OpenAI crawlers in their server configuration. It is important to understand the difference between two distinct OpenAI agents:
- GPTBot: A crawler that collects public content for training future Foundation Models. Many publishers block it to protect their copyrights.
- OAI-SearchBot: A specialized search crawler that performs real-time indexing ONLY for ChatGPT Search's needs and provides direct links to your website.
If your website's root robots.txt file blocks OAI-SearchBot, ChatGPT Search will never be able to cite your services or articles. The correct configuration involves explicitly allowing access for the search crawler while maintaining control over content indexing:
User-agent: OAI-SearchBot
Allow: /
User-agent: ChatGPT-User
Allow: /

User-agent: GPTBot
Disallow: /private/
Allow: /blogs/
This configuration ensures that your public content, service pages, and expert articles created with an AI blog engine are fully accessible to the real-time AI search engine, while internal systems remain secure.
The llms.txt Manifest as a Company's Digital Passport
As we explained in detail in our main article on creating the llms.txt file and preparing entities, by 2026, every serious website must maintain a structured factual summary in Markdown format in its root directory. ChatGPT Search and other large language models primarily scan /llms.txt to instantly obtain an authoritative list of the company's services and competencies.
By placing short, fact-based company descriptions with links to in-depth sections in this file, you ensure that the search engine always receives the correct data without hallucinations or distortions.
The Technical Duel - Google Search vs. ChatGPT Search
Let's examine the differences between the two leading search platforms in a technical comparison matrix:
| Functionality | Traditional Google Search | Modern ChatGPT Search |
|---|---|---|
| Result Presentation | List of 10 blue links with ads and snippets | Single structured answer with direct source citations |
| Primary Ranking Factor | Backlinks and keyword density | Factual accuracy, entity authority, and semantic relevance |
| User Effort | Requires opening 3 to 5 different pages and self-reading | Answer received instantly; links serve as fact verification |
| Ad Saturation | Up to 4 ad blocks above organic results | Minimal ad noise; emphasis on pure content synthesis |
| Content Format Requirement | Long SEO texts with frequent keyword repetitions | Short, self-sufficient knowledge blocks (Atomic Knowledge Blocks) |
Alongside organic presence, ChatGPT and AI search ads are also rapidly developing, providing prioritized brand exposure in direct answer blocks.
Passage-Level Citability - How to Build a Citable Content Fragment
For your website to become ChatGPT Search's primary source, each content section must adhere to the Three-Stage Citability Formula:
- Definition in the first sentence: Start each H2 or H3 section with a direct, unambiguous statement. For example: 'Server-Side tracking is a data processing model where analytics events from the user's browser first arrive at the company's server and only then are transmitted to advertising networks.'
- Factual data and comparison: Add specific numbers, percentages, or technical protocols that support the statement. AI models love facts and select them for citation much more frequently than general opinions.
- Structured list or table: Always format complex processes with a numbered list or a table. The synthesis algorithm can easily integrate such a structure into the final answer.
How OAI-SearchBot Interprets JavaScript and Dynamic Web Frameworks
One of the most serious technical errors made by modern website developers is an over-reliance on Client-Side Rendering (CSR) in libraries like React, Vue, or Angular. While Googlebot has learned to execute JavaScript, it requires enormous computational resources and a significant time delay (Rendering Queue).
OpenAI's real-time crawler OAI-SearchBot operates under much stricter time and resource constraints: if the server does not return clean, prepared HTML code with ready text within the first 500 milliseconds, the crawler does not wait for complex JavaScript scripts to execute and abandons the page. Therefore, in 2026, Server-Side Rendering (SSR) or statically generated HTML with Nginx micro-caching is an absolute prerequisite.
Semantic Entity Linking with Wikidata and Schema.org
For the ChatGPT Search model to accurately recognize your company as an expert in a specific industry, a good article alone is not enough. The search engine's Knowledge Graph relies on global entities and their interconnections:
- sameAs link integration: The website's
Organizationschema must include links to the company's official profiles on LinkedIn, Lursoft/Company Register, Wikipedia, or industry associations. - Author Expertise Markup (Person Schema): Each article is associated with a specific author, including their experience description and publication history, strengthening E-E-A-T signals.
- TechArticle and FAQPage Data Structures: By adding definitions and question-answer pairs in JSON-LD format, you ensure that the synthesis engine reads facts without semantic noise.
How to Create a Content Update Cycle and Freshness Signals
OpenAI's synthesis model pays special attention to date and content freshness signals (Freshness Factor). Unlike Google, where an article written in 2018 with thousands of backlinks can remain at the top for years, the ChatGPT search engine looks for the latest, recently verified facts and 2026 data.
To prevent your content from losing its place in the AI citation window, a dynamic content update protocol must be implemented in your website engineering:
- dateModified structured data: The article's Schema markup must be updated with the last modification time (in ISO 8601 format) as soon as data or prices are clarified in the text.
- Annual review of fact and price tables: All comparison tables must be marked with the current year, clearly indicating the latest market situation.
- Elimination of outdated external links: If the text contains links to resources that return 404 errors, the AI crawler perceives this as unmaintained content and lowers the citability rating.
Real-world Example - How a B2B Company Gained 42 Percent New Traffic
Let's look at a practical example from the industrial logistics sector. A company whose website featured classic, keyword-stuffed service texts received no visitors from artificial intelligence assistants. After a full content restructuring:
- A public
/llms.txtmanifest was implemented with precise warehouse parameters and square meter prices. - Each service page was supplemented with 3 self-sufficient knowledge blocks, where the first sentence provided a clear definition.
- The robots.txt file granted a green light to OAI-SearchBot and ChatGPT-User crawlers.
As a result, within three months, the company began regularly appearing as the primary source for queries about specialized logistics estimates, gaining 42% more qualified inquiries without increasing its advertising budget.
ChatGPT Search Readiness Checklist
Frequently Asked Questions about ChatGPT Search and Website Optimization
Does ChatGPT Search bring real visitors to a website?
Yes, and the conversion rate of this traffic is often 2 to 3 times higher than in regular Google search. A user who clicks on a source link in a ChatGPT answer has already received a basic answer and is looking for a specific service provider, estimate, or in-depth collaboration opportunity.
How can I see visitors from ChatGPT Search in GA4 analytics?
This traffic typically appears under the source 'chatgpt.com' or 'android-app://com.openai.chatgpt' with a channel group of Referral or Organic Search. It is recommended to create a separate reporting segment to track micro and macro conversions generated by AI search engines.
How long does it take for OAI-SearchBot to index new website articles?
On technically well-ordered websites with fast server response and an updated XML sitemap, OAI-SearchBot can read new content within a few hours to a day after publication.
Want to strengthen your brand's authority in Google and new AI search engines?
Request a 15-minute strategic consultation. We'll conduct a website SEO and GEO diagnostic, preparing your content for artificial intelligence answer indexes.
Fixed budget. No hidden surcharges or forced services.